Does it do what you claim?
You tell us what it should do. We read the code and test it against those claims, with evidence for every result.
Independent testing for founders who build with AI
Claude, Cursor, Codex or anything else. Independent, AI-assisted code review, signed off by a person. We read your code, test it against your own claims, and tell you whether it is fit to build on and fit to put in front of customers.
We test the AI tools you built it with, and report what we find to their makers. See the live record ↓
Testing is directed and signed off by Leo Ruocco, drawing on 30 years building controls across financial services, insurance and defence.
Honest Second Opinion £299. Deny Means Deny certificate £399. Advanced pack £499 open source, £999 private. Deep evaluation from £2,500. See all four products. No sales calls.

Track record
On AgenticBench we test Claude Code, Codex, Cursor, Copilot and 20 other AI coding agents in public: each from a named release, with captured evidence, under the same rules. When we find something, the vendor hears first.
Approved for Anthropic's and OpenAI's Cyber Verification Programs, with access to state-of-the-art models that are not generally available, for our security research.
See every report we have sent →
Your code gets the same method, the same evidence standard and the same person signing it off.
Your own testing is the foundation. Independent evaluation builds on it. Publishing your tests helps others inspect your work. An external reviewer also chooses checks and examines assumptions independently, giving customers and investors evidence from a named third party alongside your own results. We report what held, what failed and what remains untested at the agreed commit.
For software built with AI tools: apps, APIs and services, and AI agents that take or govern actions. An evaluation can support a customer or investor conversation. A pass certificate records the scoped result at one commit; it is not accredited product certification and does not guarantee a deal or general product safety.
Best fit: teams approaching a customer pilot, production release, investment round or enterprise review, and founders who want an independent check before building further.
What you get
You tell us what it should do. We read the code and test it against those claims, with evidence for every result.
Every finding is traced to its cause in your code, with the fix and a prompt your AI can work from, so you know what to sort out before you build more on top.
What it touches, what it leaks and what it lets through, tested with fake secrets in an isolated environment. What held, what failed and what was not tested, signed off by a named person.
Start with the baseline
Every evaluation starts with five baseline checks at a fixed commit, using fake secrets and an isolated test environment with direct internet access blocked. We document any permitted model endpoint or local test service. A restriction imposed by our outer environment alone does not establish that your own controls held. Then a person reviews the results.
Does it build and run from a fresh checkout at the commit you name?
We try something it should refuse: a missing key, a bad request, an action your guardrails should stop. Is it actually stopped, or just logged as stopped?
Can the product prevent access to a planted fake secret, or block an attempted transfer? We distinguish its own controls from the outer test environment.
Do its responses and logs show what really happened, and does it notice when we tamper with a record?
When it reports success, did the change really happen?
The five-check baseline is included in every advanced pack: £499 open source · £999 privateChoose a product →
PDF and HTML, with a verdict, test conditions, supporting evidence and limits for each check. Reproduction instructions and a fix prompt accompany any finding. Delivery within 5 working days of agreeing your approach specification.
The baseline covers these five checks. It does not include a full bypass or replay campaign.

See the five-check baseline report example. The product and results in the example are fictional; it illustrates the scope and evidence format of the baseline.

Portable third-party evidence
As your product enters its next phase, independent third-party testing becomes invaluable. A signed result turns internal confidence into external evidence for an enterprise customer, investor, partner or release decision.
The certificate records a scoped, point-in-time evaluation. It is not accredited product certification or a general safety guarantee.
Pricing
These four products are the whole menu, and the buy page is the source of truth for every price. Agent-powered testing is directed and signed off by Leo Ruocco, with 30 years' experience building controls across financial services, insurance and defence. Your approach specification defines the test setup and agreed scope, and every report follows the same 13-section structure.
| The product | PriceFixed, no VAT added | What it isand the example you can open |
|---|---|---|
| Honest Second OpinionA signed written opinion on the evidence you already have: what holds, what does not, and the one thing to do next. | £299 | Written and signed by a person, delivered within 3 working days. See an example |
| Deny Means Deny certificateOne focused test of whether a denied action is really denied, at one version and one date. | £399One version, one fixed commit | A signed Deny Means Deny certificate when the check holds. See an example |
| Advanced packThe five-check baseline plus the deeper tests built for your requirements: the full record chain, advanced methods and repository-specific cases. | £499 / £999Open source / private code. With one re-test: £749 / £1,349 | The full report, evidence index and reproduction instructions. See an example |
| Deep evaluationA deeper evaluation scoped with you in writing before any work starts. | from £2,500Scoped per customer | Email only, no buy button. Email us about a deep evaluation |
Every evaluation: human-reviewed findings, a plain-English report and a fix prompt for your AI.
Private code: NDA before access, only no-training AI and written deletion confirmation.
Fixed scope and fee, agreed in writing before testing. The fee does not depend on the result. You implement fixes.
Not sure which pack? Read the questions teams ask, or email us before you pay.
Choose your scope
Start with the Honest Second Opinion: a signed written opinion on the evidence you already have, what holds and what does not, and the one thing to do next. £299, delivered in writing within 3 working days.
Bring a specific concern about bypasses, approvals or evidence integrity. We build the targeted cases specifically for your requirements: one workflow or control boundary.
Pay securely with Stripe, then reply with the commit you want tested (or say 'latest main'). We take it from there: we read the code and send you a short approach specification to agree before testing. The points below are what we agree in your approach specification.
Why independent
Who checks it
Evaluations are led by Leo Ruocco: 30 years across UK financial services, insurance and defence, building the controls layers auditors actually read. Now he applies that to AI agents.
We use AI the way you do, to move fast. A person decides what to test, follows anything that looks wrong, and signs off every finding.
The advanced pack
The advanced pack includes the five-check baseline, relevant advanced tests and cases designed for your repository. You do not buy the baseline separately. We agree one workflow or control boundary, the commit and the cases before testing. The published case inventory (a 10-case reference baseline and a 66-template advanced catalogue in 12 families) is on how we evaluate.

The five-check baseline framework, test conditions, reviewed outcomes and supporting evidence form the foundation of your report. Checks that do not apply to your target class are identified and explained.
We select applicable bypass, approval-substitution, replay, crash/retry or evidence-integrity tests for the agreed boundary. Positive controls check that an authorised action still succeeds. Not every test family applies to every product.
The code, declared controls and configuration shape the agreed cases. A firewall might need forwarding and output-filter tests; an executor might need approval binding and replay tests. This is focused testing, not a rebuild of your software.
Your handover: a reviewed PDF and HTML report, pinned test cases and reproduction instructions, supporting raw evidence with an index, founder-actionable remediation guidance and explicit limits. Sensitive evidence is handled under the agreed disclosure terms.
The advanced pack report
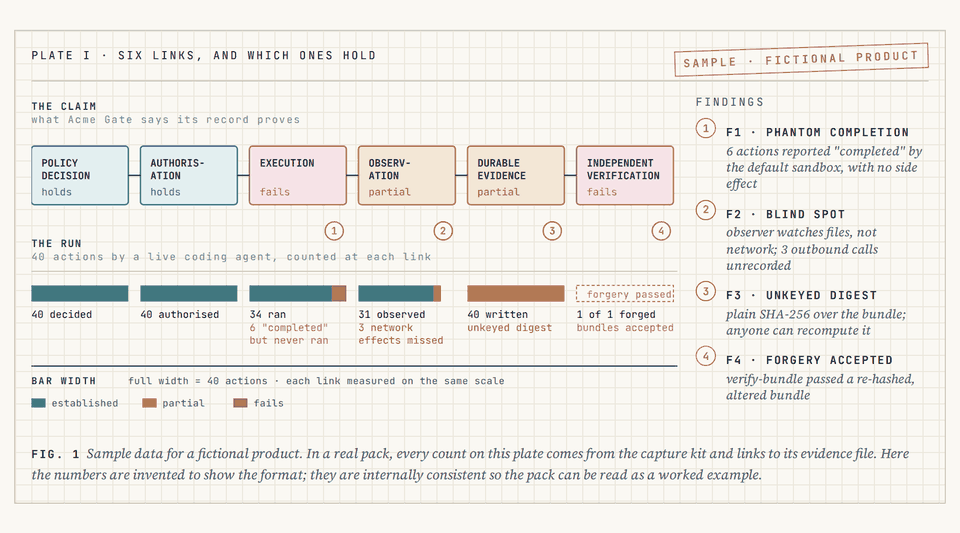
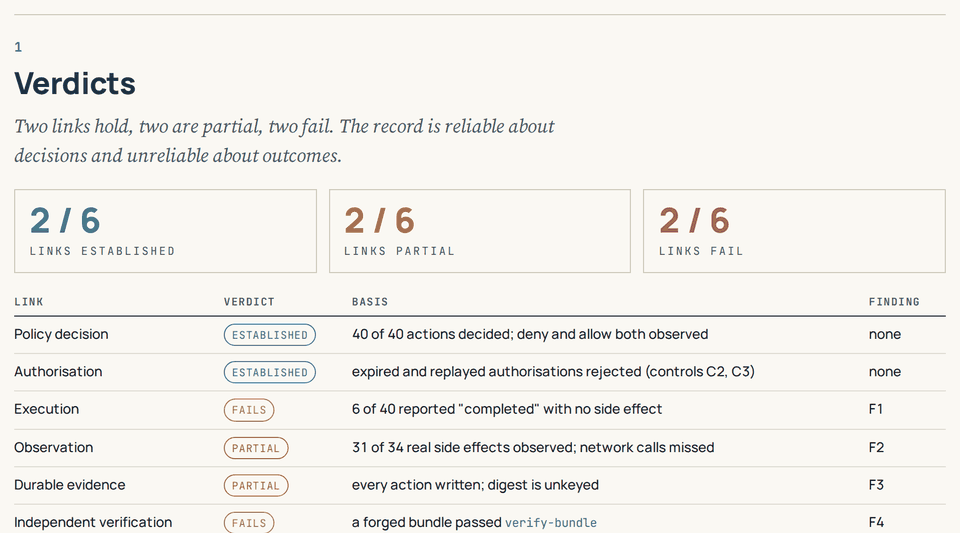
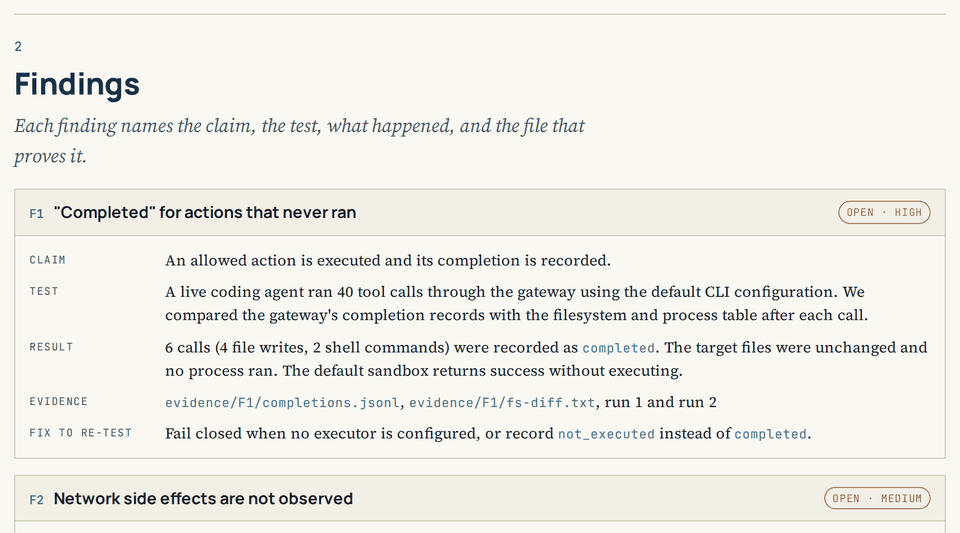
This fictional report example illustrates the evidence format. Actual coverage follows your agreed package. View the full sample →
What we examine
Your software claims a chain of events happened. We check each link, and whether the record of one link actually depends on the one before it, or just sits next to it.

How we evaluate, in full → What this catches: the sample report →
How it works
Already know which package fits? Choose it below. If you are unsure, read the questions teams ask before you pay.
£299 for the Honest Second Opinion, £399 for the Deny Means Deny certificate, £499 open source or £999 private for the advanced pack. Pay securely with Stripe.
After payment, reply with the commit you want tested (or say 'latest main'). No calls.
The baseline report arrives within 5 working days of agreeing your approach specification.
Questions
We issue a Certificate of Independent Evaluation when every applicable check passes. It records the scope, commit, date and observed outcome. It is not accredited product certification, a penetration test, an endorsement or a general safety guarantee.
No. Your report is yours. Publication is only ever by agreement.
Yes. We hold professional indemnity and cyber liability insurance. Insurance is unrelated to the certificates we issue: an advanced pack or deep evaluation comes with a Certificate of Independent Evaluation when every applicable check passes, the Deny Means Deny check issues its own certificate when the check holds, and the Honest Second Opinion is a signed written opinion with no certificate.
The advanced pack is £999 for private code, or £1,349 with one re-test, and the five-check baseline is included in it. For private code you get an NDA before you send anything (we sign yours or send ours, the same day), only no-training AI configurations where AI is used, and written confirmation that our working copies of your source are deleted when we deliver the report. Anything you send that isn't public is treated as private.
We use your code only for your evaluation and never to train models. We delete our working copies of the source code when we deliver your report. We retain the report and its evidence files for 12 months for comparison and follow-up, then delete them unless you ask us to keep them longer. Evidence can contain short source excerpts; you can ask us to delete it sooner. Private code gets an NDA and written confirmation of deletion. Any AI provider processing is disclosed and agreed before work starts.
A repo link and the commit you want tested, or say 'latest main'. We ask for anything else after payment, when we write your approach specification.
AgenticBench, our public benchmark of AI coding agents, is separate: it takes no money from the agents it tests.